




Sr. Director of Data Science @ Socure. I lead ML teams building real-time fraud and risk machine learning models operating at massive scale.
I work on fraud ML, agent identity and evaluation. My repos include a fault-injection test range, statistics for repeated benchmark runs, and signed credentials with delegation and revocation.
- Test an agent. Agent Retry Rodeo runs your adapter against failed tools and ambiguous writes. Start with the offline replay; connecting a model is a separate step.
- Compare repeated runs. agentstats checks run-to-run variance and pairwise differences. Install from Git; the PyPI namesake is unrelated.
- Verify delegation. Know Your Agent checks signed credentials, delegation chains and revoked permissions. Demo only; no payments.
- Read the research. AgentRisk measures fraud-policy behavior on a semi-synthetic benchmark. Its rates are benchmark results, not production estimates. Preprint, not peer-reviewed.
Everything here is synthetic data or public data. No Socure production data, no real transactions, no real PII, anywhere on this profile.
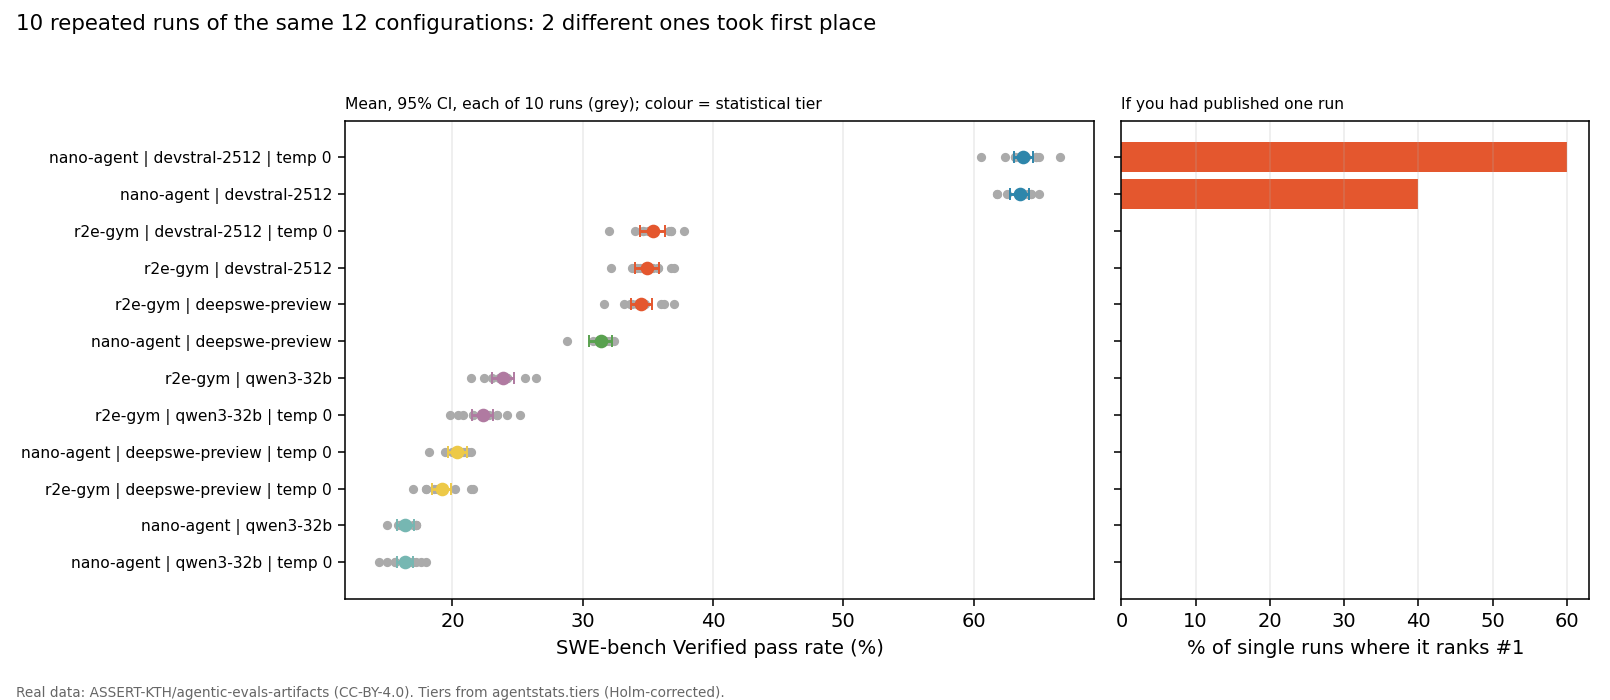
agentstats: Ten repeated runs of the same 12 agent configurations. Two statistically tied agents swap first place, so a single published run can crown either one. Real data from ASSERT-KTH (CC-BY-4.0).
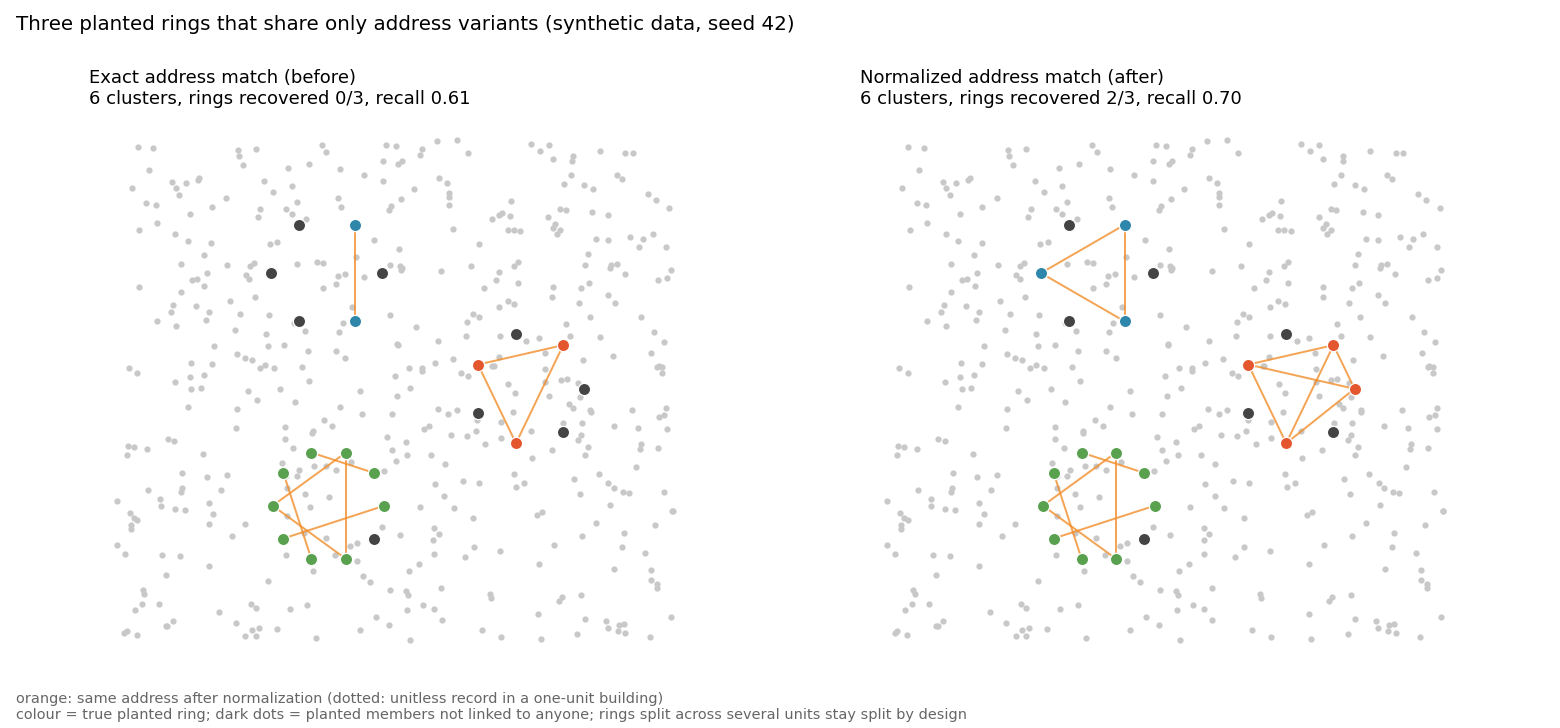
fraud-rings: Address normalization recovers 2 of 3 planted rings that exact matching misses. The ring spread across several apartment units stays split on purpose. Synthetic data.

stream-fraud: Drift replay over 20 seeds. PSI alarmed earlier than a KS test here, and neither is false-alarm free. Synthetic data.
Know Your Agent now authorizes delegated purchases over HTTP: verify the whole credential chain, block revoked permissions, then enforce the final agent's spending and category limits. Optional audit logging records the decision. Still a demo, not a payment service.
Agent Retry Rodeo can export before/after regression comparisons as JUnit XML for CI report viewers. Passing means no new regression, not that the agent completed its task.
Tiny ML Lab can check workbook feedback across days in one command, with per-workbook timeouts and text or JSON output. TODOs stay visible; self-check feedback is not correctness grading.
I also fixed agentstats' exact-test run planner to reject invalid significance levels instead of hanging or returning misleading run counts. Valid-input results are unchanged.
- ... you want to beat a seed sweep. In GNN-fraud-ring-detection's synthetic demo setup, mean aggregation drops to AUC 0.728 / 0.539 on seeds 8-9 while max-pool, LSTM and GIN aggregators hold 1.000. Synthetic data, three seeds: a demo result, not a benchmark. Add your own aggregator and run the sweep. Pure Python, zero dependencies.
- ... you want a workbook, not a gallery. tiny-ml-lab is built to be forked: fill in each workbook.py, check days off in your own PROGRESS.md, add a row to the SHOWCASE.md hall of fame, and vote the next algorithm up the queue in REQUESTS.md.
- ... you want an unclaimed task. Time-series-anomaly-detection has four on its roadmap: multivariate series with cross-channel attention, Informer-style sparse attention for long windows, streaming inference without re-encoding the window, and learned threshold calibration. Pick one and open a PR.
Evaluation, statistics and benchmarks
| Repo | What it is |
|---|---|
| agentstats | Run-to-run variance, significance tests and minimum-runs planning for AI agent benchmarks. Install from Git (the PyPI name belongs to another package). |
| fraud-eval | Open benchmark for LLM-based fraud and abuse detectors. v0.1.0 is a 20-case smoke test with a Hugging Face dataset and leaderboard. |
| agentrisk | Benchmark and code for the preprint "Automation Is Not Intent": how fraud models treat legitimate AI shopping agents. |
| feature-contracts | Reproduction package for the feature-contracts manuscript, using public datasets. |
Fraud and anomaly detection, from scratch in pure Python (synthetic data)
| Repo | What it is |
|---|---|
| GNN-fraud-ring-detection | GraphSAGE, GAT and other graph networks with no dependencies, applied to fraud rings in transaction networks. |
| fraud-rings | Synthetic ring generator plus shared-attribute linking with union-find. |
| stream-fraud | Streaming scoring pipeline demo: velocity features, rule-based scorer, PSI and KS drift detection. |
| Time-series-anomaly-detection | Transformer autoencoder for collective and contextual anomalies. |
| ID-document-forgery-detection-CV- | Classic image forensics on synthetic ID cards with planted forgeries. |
| agentic-fraud-investigator | Multi-agent case investigation: triage, evidence, risk score, analyst-style report. Runs offline with a mock LLM by default. |
Agents
| Repo | What it is |
|---|---|
| know-your-agent | Scoped, session-limited, revocable agent credentials signed with Ed25519, with delegation chains, a signed hash-chained audit trail, a benchmark hook, and a FastAPI demo. v0.2.0. |
| agent-retry-rodeo | Local test range for agent recovery: watch "done" fail against a fault, then replay a recovery-aware baseline. |
Learning
| Repo | What it is |
|---|---|
| tiny-ml-lab | One classic ML algorithm a day, numpy only, with a workbook to fill in. |
Presented as separate projects; no integrated pipeline is claimed here.
- Peer review, 16 completed: IEEE Access (2), Knowledge-Based Systems (4), Pattern Recognition (4), IEEE Transactions on Big Data (1), Expert Systems with Applications (2), Data Mining and Knowledge Discovery (1), Computers and Security (1), ACM Transactions on Knowledge Discovery from Data (1). 16 posted on Web of Science as of Nov 11, 2026. Peer reviewer badge above names two venues only, the full list is here.
- Papers under peer review, 0 published yet: FATT, IEEE Access, Access-2026-52664; Selection-Aware Certification, IEEE Access, Access-2026-55371; Feature Contracts, EAAI, EAAI-26-34856; Counterfactual Evaluation, SN Computer Science transfer, no manuscript number yet. Goal: 2 peer-reviewed journals plus 2 peer-reviewed conferences.
- Revising: Testing published state-of-the-art claims, after an editorial decision at Science and AI (Nov 9, 2026), not currently under review.
- Preprints, not peer-reviewed: AgentRisk, Zenodo DOI 10.5281/zenodo.23477625; fraud-eval, Zenodo DOI 10.5281/zenodo.23695132.
- Conferences: ICMI2027 submitted, CMT Paper ID 157; SAI Computing Conference 2027 submitted, Paper ID COMPUTING-2027-105; AgentRisk targeted at ICFEC 2027, Dec 20, 2026, and AIML 2027, Feb 26, 2027.
- Program Committee: IJCNN 2027
- Co-inventor on pending patent applications in AI-driven fraud detection (US + EP). FATT, US App. 18/381,381, notice of allowance received, issue fee paid Oct 2, 2026.
Name on all of them: Rishabh Pande. ORCID iD wherever a field exists: 0009-0004-1901-7109. Paper bylines use Independent Researcher, employment is Socure, that difference is deliberate.
Currently building in public. New commits land daily.